Aiserveon Aiserveon

Top 10 NVIDIA GPU Server Manufacturers for Global Buyers

Time:2026-10-17 Author:Sophia
0%

Choosing the right NVIDIA GPU server partner can shape an entire AI, research, or high-performance computing project. The best systems must balance GPU performance, thermal design, power efficiency, serviceability, and long-term support. A reliable nvidia gpu server manufacturer should explain these choices clearly, not hide behind impressive benchmark numbers.

Small details matter. A well-designed server may include redundant power supplies, high-speed networking, tool-less drive access, and airflow suited to dense GPU workloads. Cooling is especially important when several accelerators operate continuously inside a compact chassis. In real deployments, unstable temperatures can reduce performance and increase maintenance costs. This guide examines ten manufacturers serving global buyers, using practical criteria rather than marketing language alone. Product availability, warranty coverage, technical support, certifications, and customization options all deserve attention. A lower purchase price is not always a lower total cost.

No ranking is perfect. Vendor strengths can change with supply conditions, new GPU generations, and regional service capacity. Some manufacturers excel at standardized systems, while others provide more flexible engineering support. Buyers should still verify current specifications, delivery estimates, software compatibility, and local warranty terms before signing an order. That step is easy to overlook.

The comparison also considers how each company supports deployment after delivery. Documentation, remote troubleshooting, replacement procedures, and firmware updates can matter as much as raw computing power. Global customers may need different power standards, rack configurations, import documentation, or data-center requirements. These practical differences can affect project schedules. The following overview offers a structured starting point for evaluating leading NVIDIA GPU server manufacturers with greater confidence, caution, and technical clarity.
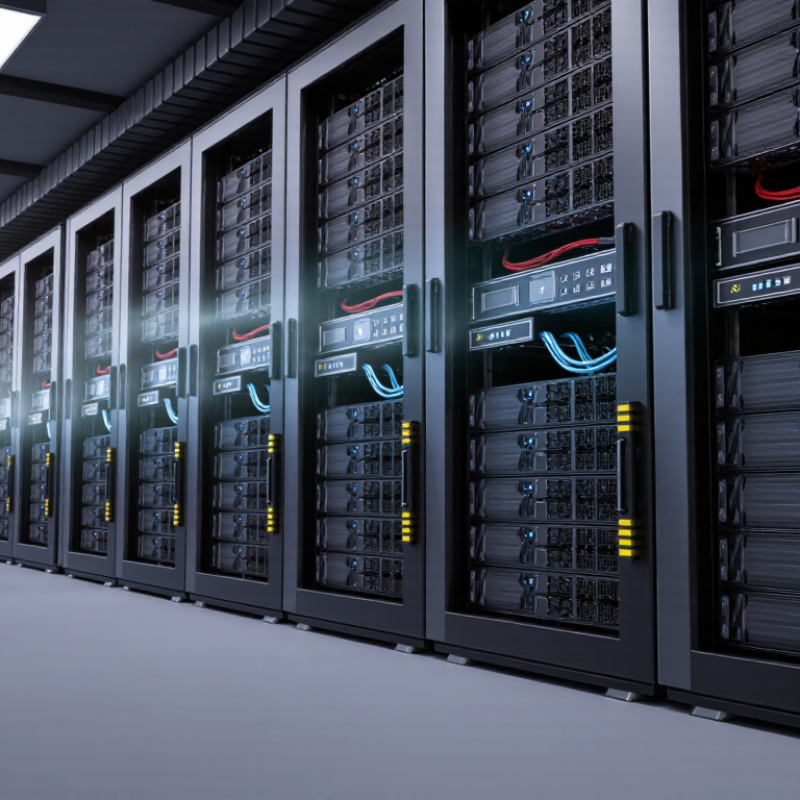
Top 10 NVIDIA GPU Server Manufacturers for Global Buyers

How NVIDIA GPU Server Manufacturers Are Evaluated

Evaluating NVIDIA GPU server manufacturers requires more than comparing processor counts. Experienced buyers inspect the complete platform: GPU configuration, CPU balance, memory capacity, storage speed, and network bandwidth. A powerful accelerator can still underperform when data arrives too slowly. Real workloads reveal this quickly.

Thermal design deserves close attention. Review airflow paths, fan redundancy, rack density, and documented operating temperatures. Ask for measured performance under sustained eight-hour workloads, not only short benchmark results. Power delivery also matters. A server drawing heavily from each rack outlet may increase operating costs and complicate data-center planning. Practical manufacturers provide clear power estimates, acoustic data, and service procedures.

Software readiness separates reliable suppliers from attractive spec sheets. Check driver validation, virtualization support, container compatibility, monitoring tools, and firmware update methods. Request logs from comparable deployments when possible. Support quality should be tested before purchase: response times, spare-part access, escalation processes, and technician coverage matter during a failed node event. Security controls and regional compliance documentation should be equally clear.

Evaluation is rarely perfect. Benchmarks may not match your models, datasets, or cooling conditions. I would run a pilot with real inference or training jobs, record temperatures, and compare throughput per watt. Unexpected bottlenecks often appear there. Leave room for doubt. Claims deserve evidence, and evidence should remain reproducible.

Top 10 NVIDIA GPU Server Manufacturers for Global Buyers

Global GPU server buyers need more than a familiar product name. A credible top-ten manufacturer list should examine accelerator compatibility, thermal design, power delivery, and regional support. IDC reported that worldwide artificial intelligence infrastructure spending reached an estimated 154 billion dollars in 2024, growing 44.8% year over year. That growth increases choice, but also increases procurement risk.

Real testing matters. Compare inference throughput, training performance, memory capacity, and rack density using the same workloads. The MLPerf Training and Inference results show that system performance depends on software tuning, networking, and storage, not only accelerator count. A server with eight processors may underperform a better-balanced four-processor system. On-site details matter. Ask about 40-kilowatt rack readiness, liquid-cooling options, spare-part locations, and firmware validation.

Power deserves closer attention. The International Energy Agency projects data-center electricity demand could more than double by 2030, driven partly by artificial intelligence workloads. Buyers should request measured power figures, not optimistic estimates. Warranty language also needs inspection. Some suppliers provide impressive specifications but limited overseas repair coverage. That is a weakness worth admitting. Delivery times can change, too. A practical shortlist should score technical performance, lifecycle cost, compliance documentation, and support response times, then verify every claim through independent testing and customer references.

Key GPU Server Features, Platforms, and Deployment Options

Top 10 NVIDIA GPU Server Manufacturers for Global Buyers

GPU server selection now depends on more than accelerator count. Practical evaluations should check memory capacity, high-speed interconnects, PCIe bandwidth, and airflow design. A server with eight GPUs may underperform when storage or networking becomes a bottleneck. Small details matter.

The International Energy Agency estimates that data centers could consume between 620 and 1,050 TWh of electricity globally by 2026. Therefore, buyers should examine power efficiency, liquid-cooling readiness, rack density, and workload-based utilization. Uptime Institute’s 2024 Global Data Center Survey also highlights power availability as a major infrastructure concern. Redundant power supplies and clear thermal monitoring are not optional features for demanding deployments.

Platform choice changes daily operations. Bare-metal systems provide direct control for model training and performance testing. Kubernetes-based platforms improve scheduling across shared GPU pools. Managed cloud environments simplify scaling, but may increase long-term operating costs. Hybrid deployment can keep sensitive workloads on premises while handling temporary demand externally. According to IDC, worldwide spending on AI-centric systems continues to expand rapidly, yet procurement decisions often remain too focused on peak specifications. That is a weakness worth questioning. Real performance depends on software drivers, orchestration, data pipelines, and technician support. Short benchmarks can mislead. Load tests should reflect actual batch sizes, model formats, cooling conditions, and failure recovery procedures.

Regional Strengths, Support Services, and Compliance Factors

For global buyers, the top ten GPU server manufacturers should be judged beyond hardware specifications. Regional strength affects delivery times, spare-part access, and engineering response. A supplier with local integration teams can validate rack depth, power limits, and cooling requirements before shipment. In Southeast Asia, humidity planning matters. In Europe, energy efficiency and documentation may receive closer attention. North American buyers may prioritize rapid replacement and data-center compatibility. These differences make a universal ranking imperfect.

Support quality reveals real expertise. Ask whether technicians provide burn-in reports, firmware guidance, remote diagnostics, and documented escalation paths. Confirm service hours across time zones. Compliance also needs evidence, not promises. Manufacturers should explain component traceability, export screening, safety certifications, electromagnetic testing, and secure data-handling procedures. Buyers should verify local import rules and facility standards. I have seen attractive quotations fail because power requirements were underestimated. That mistake is costly and avoidable, yet specifications are sometimes unclear.

Tips: Request a regional service map, sample compliance documents, and written response-time commitments. Compare warranty exclusions carefully. Test escalation before purchase. A short technical call can expose weak support. Keep room for uncertainty; projected workloads often change after deployment.

How to Choose the Right NVIDIA GPU Server Manufacturer

Choosing a GPU server manufacturer starts with your workload, not a glossy product page.

Define model size, training duration, inference latency, and expected user volume. An experienced supplier should explain GPU memory, interconnect bandwidth, cooling limits, and power draw in practical terms. Ask for benchmark results using workloads similar to yours. Generic charts can mislead. Request component records, burn-in reports, and clear warranty terms. Reliable manufacturers also disclose lead times and replacement procedures before accepting payment.

Inspect the complete platform, not only the accelerator.

Check CPU balance, memory channels, PCIe topology, storage endurance, network speed, and rack density. A server can contain powerful GPUs yet underperform because airflow is restricted or data feeds arrive slowly. Ask whether technicians provide remote diagnostics and regional support. Verify certifications, firmware practices, and security controls. Talk with existing customers when possible. Their maintenance stories often reveal more than polished demonstrations.

Price deserves careful interpretation.

Compare total operating cost, including electricity, cooling, support, spare parts, and software integration. A low purchase price may become expensive after repeated downtime. Manufacturers should offer configuration validation, acceptance testing, and documented performance targets. Be cautious when claims sound perfect. They rarely are. Request a pilot unit before a large order, especially for mixed workloads or unfamiliar facilities. Leave room for future GPU, memory, and network upgrades; rigid designs age quickly.

FAQS

What should buyers evaluate besides GPU count?

Check CPU balance, memory capacity, PCIe bandwidth, storage speed, and network throughput. More GPUs do not guarantee faster results.

Why does thermal design matter in a GPU server?

Restricted airflow can reduce performance during long workloads. Review fan redundancy, rack density, cooling limits, and measured temperatures.

How should sustained performance be tested?

Request an eight-hour workload test using similar models, datasets, batch sizes, and cooling conditions. Short benchmarks can mislead.

Which power details should manufacturers provide?

Ask for power estimates, rack-level consumption, cooling requirements, and operating costs. A power-hungry server may complicate facility planning.

What software capabilities deserve inspection?

Verify driver validation, virtualization, container support, monitoring tools, and firmware updates. Software readiness affects daily reliability.

How can buyers judge technical support?

Ask about response times, spare-part access, remote diagnostics, escalation procedures, and regional technicians. Support matters during a failed-node event.

Which deployment model suits different workloads?

Bare-metal systems offer direct control. Cluster platforms improve shared scheduling. Managed environments simplify scaling but may cost more over time.

How should the total cost be compared?

Include electricity, cooling, support, spare parts, software integration, and downtime. A cheap purchase can become expensive later.

Should buyers request a pilot unit?

Yes, especially for mixed workloads or unfamiliar facilities. Record throughput, temperatures, recovery behavior, and power use. Some surprises are useful.

What evidence should manufacturers provide before purchase?

Request component records, burn-in reports, warranty terms, lead times, acceptance tests, and comparable deployment results. Perfect claims deserve doubt.

Conclusion

Choosing the right nvidia gpu server manufacturer requires more than comparing hardware specifications. Global buyers should evaluate manufacturers by GPU compatibility, server architecture, performance consistency, thermal design, energy efficiency, production quality, warranty coverage, and long-term technical support. The strongest providers offer flexible platforms for AI training, inference, scientific computing, visualization, and enterprise workloads, with deployment options ranging from compact workstations to rack-scale systems and customized data center solutions.

Regional availability, logistics capability, service response times, compliance documentation, and integration expertise are also essential considerations. Buyers should examine supported GPU configurations, CPU and memory balance, storage expandability, networking options, remote management, and software ecosystem compatibility. A careful selection process should match the manufacturer’s engineering strengths and support resources with the organization’s workload, budget, deployment location, scalability plans, and operational requirements. By assessing these factors together, businesses can reduce implementation risks and build a reliable GPU infrastructure for both current projects and future growth.
Sophia

Sophia

Sophia is a dedicated marketing professional with an exceptional depth of knowledge about her company's products and services. With a keen understanding of market trends and customer needs, she crafts insightful blog posts that not only inform but also engage readers, enriching the company’s online......